0% READ
FULL TEXT
INTRODUCTION
The utility of citation indices for evaluating research impact has long been a subject of divergent views. While some scholars argue that citation indices perfectly reflect the value of research (Lazarev, 2021), others describe them as a cuckoo in a nest (Lawrence, 2007). Regardless of these differing perspectives, mathematical models often employ the law of chance to account for highly cited papers (Simkin & Roychowdhury, 2011). This study makes an attempt to understand how citation metrics affect the chances of winning the Nobel or Abel Prize. This analysis has the potential to offer insights into the contribution of intellectual or network-based attributes (often captured by the Q-factor) to ground-breaking achievements. The importance of this study can be assessed in the following contexts.
The influence Siα of a publication α authored by researcher iα function of the potential impact pα of the paper.
Identifying common traits among Nobel and Abel Prize winners that help define what characterizes groundbreaking scientific or mathematical research.
Informing predictive tools for identifying future high-achieving researchers based on Q-Factor benchmarks.
Revealing the impact of collaborative networks, mentorship patterns, and institutional support on research impact.
Highlighting ethical questions relating to whether high recognition in academic disciplines is based more on network visibility or the intrinsic merit of the research work.
Nobel and Abel Prizes
In the context of scientometrics, which monitors and examines scientific outputs and their effects, the Nobel and Abel Prizes are esteemed international honors that are very valuable. Established in 1901, the Nobel Prizes honor pioneering work in fields like economics, physics, chemistry, medicine, literature, and peace. In a similar vein, the 2001-established Abel Prize only recognizes outstanding contributions to mathematics. These honors are important markers of intellectual standing and scientific brilliance, frequently impacting research funding dynamics, collaboration networks, and citation trends. These awards serve as crucial milestones in the assessment and mapping of scientific impact across fields, as its recipients often demonstrate a notable increase in scholarly recognition and influence.
Motivation Behind the Study
The on-going discussion about the fairness and efficacy of citation metrics in evaluating the worth of research and its influence on winning renowned prizes like the Nobel or Abel Prize is what inspired this study. Citation metrics have been questioned for their possible biases and limits, while being frequently employed as measures of scholarly influence. Critics compare citation indices to a "cuckoo in a nest" (Lawrence, 2007), while supporters contend that they can correctly indicate the importance and impact of research (Lazarev, 2021). This contradiction begs the question of whether citation measures accurately reflect the intrinsic worth of research or if they are largely a reflection of network-based characteristics and visibility.
There is an opportunity to close this gap by understanding the function of the Q-factor, a composite measure of influence, collaboration, and publishing output. Key components frequently linked to academic success, such as the size of a researcher's network, the influence of their publications, and their productivity, are encapsulated in the Q-factor. The study aims to identify trends and elements that lead to groundbreaking accomplishments by examining the relationship between the Q-factor and the probability of receiving renowned prizes. The practical implications for researchers, institutions, and policymakers are another important motivator. If specific attributes, such as publication impact or collaborative networks, are highly correlated with recognition, this information could help academic institutions identify and nurture talent, and policymakers develop initiatives that support research environments conducive to high-impact work.
Furthermore, the study is driven by more general ethical and philosophical queries concerning acknowledgment and merit. The Nobel and Abel Prizes are frequently regarded as the highest honours in science and mathematics, signifying both the contributions of the larger academic community as well as individual brilliance. It may be possible to develop a more sophisticated understanding of academic success fairness by investigating if systemic factors, including network advantages or resource access, disproportionately affect such recognition.
Contribution
This study makes a significant contribution to scientometrics and search evaluation by empirically investigating the correlation between the Q-factor-a composite citation-based metric-and the receipt of prestigious awards like the Nobel and Abel Prizes, revealing moderate positive associations (0.65 for Nobel and 0.47 for Abel) through Pearson correlation coefficients and maximum likelihood estimation. It introduces a novel equation, Q=TR, where T represents true scientific talent and R accounts for luck or opportunities provided to the researcher.
For unrelated factors such as networking or visibility, thereby highlighting the limitations of citation metrics in capturing intrinsic merit, particularly in mathematics, where correlations are weaker. By analyzing large datasets from sources such as the Ad Scientific Index and prize databases, the research highlights disciplinary differences and advocates for discipline-specific assessment frameworks. It raises ethical questions about academic recognition, ultimately informing predictive tools, institutional policies, and more equitable evaluations of scholarly impact.
Paper Organization
The paper is structured to systematically explore the correlation between the Q-factor and winning the Nobel or Abel Prize, ensuring a clear and logical progression of ideas. It begins with an abstract that summarizes the purpose of the study, the methodology involved, and the key findings. This is followed by Introduction that is dedicated to contextualizing the research in the light of the ongoing debate about the efficacy of citation metrics in evaluating scholarly impact. The Literature Review critically examines previous studies on citation-based metrics and their relationship to prestigious awards, besides highlighting the gaps and inconsistencies, such as the underrepresentation of mathematicians like Andrew Wiles in citation rankings. Literature Review is followed by Conceptual Framework that explains the Q-model. The section titled Data and Materials describes the data (2,626,068 rows from the Ad Scientific Index). This is followed by Methodology section which details the quantitative research design, and statistical techniques like Pearson correlation and Monte Carlo simulations. This section also explains the parameters required for extracting data, as well as the process of extracting data from the source. The next section presents the Results. This section includes the correlation coefficients (0.65 for Nobel and 0.47 for Abel) and discusses their implications through scatter plots and statistical analyses. The penultimate section discusses the findings, emphasizing disciplinary differences and the influence of non-scientific factors. The last section concludes the study, and includes discipline-specific evaluation frameworks, supported by a comprehensive reference list.
LITERATURE REVIEW
Studies on Citation Matrix and Scientific Recognition
In their study on the association between the number of citations and the Nobel Prize, Kosmulski (Kosmulski, 2020) utilized 100,000 scientists compiled by Ioannidis and others (Ioannidis et al., 2019) as the most cited. The author observed that of the 97 scientists who had been recently awarded the Nobel Prize, the names of 90 scientists figured in the list. Furthermore, 45 scientists were among the top 6,000 scientists. Regarding the Abel Prize winners, the dataset (Ioannidis et al., 2019) listed the names of 6 of the 22 winners. Surprisingly, the list does not contain the name of Andrew Wiles, who is credited with proving the Fermat Theorem. Additionally, among the 60 Fields Medal winners, the names of 22 winners are listed. A possible cause of this observation may lie in the fact that papers on mathematics receive fewer citations than those in other sciences. Although this argument appears to be true, it is factually incorrect. The list of 100,000 most cited scientists (Ioannidis et al., 2019) contains 1.45% of all scientists and 0.93% of all mathematicians. This indicates that mathematicians have a representation that is slightly less than that of scientists. The fact remains that approximately 900 names in the list are those of mathematicians.
In their study comparing the h-index of Nobel Laureates in Chemistry and Economics, Maurya and Kumar (2022) observed that the h-index has a strong positive correlation with the likelihood of being nominated for the Nobel Prize. The h-index is calculated based on the citations that any paper has received from future researchers. The citation also includes self-citations where the author cites his/her own work in future studies. Sinatra and others (Sinatra et al., 2016) have presented a new citation-based metric referred to as the Q-factor, which is described in detail in the subsequent section. The authors have calculated this parameter for approximately 3000 physicists. The authors have presented their findings using several Receiver Operating Characteristic (ROC) curves, which demonstrate the efficacy of the classification model at all classification thresholds. Any ROC curve has two bounds: True Positive and False Positive. Interpreting ROC curves can be challenging. On careful analysis of the curves, it is observed that only five scientists among those having the highest Q-factor ranking have been awarded the Nobel Prize. It is also observed that 25 Nobel Prize winners have a Q-factor rank of more than 700.
Nobel Prizes, according to Hu & Lou (2018) and Hu & Rousseau (2017), act as catalysts for significant transformations in modern knowledge ecosystems. These articles demonstrate that not all transformative contributions are followed by large citation counts, using the Nobel Prizes as a case study. Mazloumiam et al. (2011) investigated how new concepts question and progress conventional wisdom by examining the citation patterns of 124 Nobel Laureates awarded between 1990 and 2009. In a similar vein, Tong & Ahlgren (2017) employed citation analysis of chemistry Nobel Prizes to investigate the development of four thematic themes within the field, with a special focus on the role of international cooperation. Iwami et al. (2014) conducted a case study on Shinya Yamanaka's Nobel Prize to demonstrate the efficacy of evaluating annual in-degree volatility within direct citation networks. To identify new, significant publications, they proposed a system that calculates parameters such as the slope, area, height, and time span of an article's in degree distribution. To validate their "disruptive index," a statistic designed to measure an article's impact on scientific attention, Wu et al. (2017) used Nobel Prizes as examples. The difference between the percentage of direct citations to an article and the percentage of co-citations involving the article and its references is used to compute this index.
Despite their value, these earlier methods had several drawbacks. A waiting period of five to ten years or more is required after an article's publication to evaluate its quality, due to the inherent time lag introduced by the reliance on citation information. Furthermore, because it is based on a small and selective dataset, concluding the citation patterns of just one or a small number of Nobel Prizes is not sufficiently convincing. The generalizability of results is further complicated by the fact that citation patterns might differ significantly after scientific articles are published. The limitations of citation-based evaluations are further highlighted by the fact that some excellent publications receive few or no citations for a long time after publication (Raan, 2004; Hu & Wu, 2014, 2018).
A critical review of past literature suggests imperfections in the agreement regarding the opinions of the committees that award the Nobel, Abel, and Fields prizes and citation rankings. Additionally, the citation rankings and being nominated for prizes are not entirely independent. The correlation coefficient is a statistical method used to describe the strength and direction of an association between variables. This method is generally preferred due to the convenience of using a specific number to describe the association rather than stating the number of Nobel Laureates whose names figure among the top X highly cited scientists or among the top Y highly cited scientists.
The calculation of the correlation coefficient would be easy if the Nobel Committee provided ratings to all the scientists in the pool. The absence of such ratings makes the task tricky, but not impossible. We know the ordinal ranks of the Nobel laureates in the list, organized according to decreasing citation numbers. Using this data, the correlation coefficient, which is most likely to Such a pattern can be ascertained. Citation-based indicators, such as the Field-Weighted Citation Impact (FWCI) and Mean Normalized Citation Score (MNCS), account for field differences, publication year, and type, with the FWCI using the All-Science Journal Classification system for normalization (Purkayastha et al., 2019). International co-publications, which have steadily increased over time (Wagner et al., 2015), generally demonstrate higher citation impacts than national publications, although exceptions exist depending on the country and context (Glänzel & Schubert, 2001; Glänzel, 2001). Peer review data also support the higher quality of international co-publications (Thelwall et al., 2024). The rising number of co-authors, including those in hyper-authored papers, further complicates citation analysis. Hyper-authored publications, often involving hundreds of authors and multiple countries, exhibit citation impacts twice the global average (Thelwall, 2020), although they may distort national comparisons (Kahn, 2018). Fractionalized methods are recommended to address disparities caused by co-authorship and international collaboration (Aksnes et al., 2012; Puuska et al., 2014). Approaches to normalize citation impacts include categorizing publications into single-author, national, and international collaboration groups, as proposed by Adams et al. (2019) and Potter et al. (2020). Studies also highlight variations in citation impact based on the number of co-authors or collaborating countries, emphasizing the need for tailored analyses for publications involving extensive collaborations (Adams, 2018).
Studies Expanding the Scope of the Q-factor to Other Prestigious Awards
While the initial work on the Q-factor by Sinatra et al. (2016) was related to winning the Nobel Prize, later studies have expanded the application of the metric to include other awards. The aim of these studies lies in testing how Q-factor can be generalized across various academic fields.
Fields Medal
The Fields Medal is awarded to mathematicians having age less than 40 years. Simkin (2021) used the Q-factor and other citation indicators to examine the rankings of prize winners. The study calculated the correlation coefficients by maximizing the likelihood of the observed rank patterns. A correlation of approximately 0.59 between composite citation indicator and winning the Fields Medal was observed. The lower correlation suggests that while the Q-factor captures some aspect of mathematical eminence, its effectiveness is structurally limited by the slower, lower-volume citation culture inherent to mathematics (Simkin, 2021). The reliance of the Q-factor on citations in the first 10 years fails to capture the delayed but deep impact that are often recognized by these mathematical committees.
Turing Award
Turing Award is also called the Nobel Prize of Computing. Very limited number of studies has assessed the validity of the Q-factor in predicting the chances of winning the Turing Award. However, Yuan et al. (2021) have provided an indirect assessment of the Q-factor's utility in Computer Science (CS). The authors have observed that neither high productivity nor a high h-index was the sole indicator for winning this award. The authors have concluded that as the Q-factor overcomes the bias of the h-index a metric like the Q-factor would be better suited for evaluating CS elites than conventional measures. The selection criteria for the Turing Award highlight breakthrough work having a long-lasting impact. This criterion aligns with the theoretical goal of the Q-factor, that measure sustained ability rather than cumulative output.
General Awards
In order to analyze scientific excellence across various fields, the Q-factor has been alternately defined as the ratio of the maximum achievement to average achievement. Several studies have used the alternate definition of the Q-factor to analyze citation inequality. Biswas et al. (2021) have observed that high levels of citation inequality are associated with winning high-repute prizes across Physics, Chemistry, and Economics. The authors have argued that excellence correlates with disparity. This expands the principle of separating outstanding impact from average performance. This is the basic idea of the Q-factor which has been applied to a wider range of high-level awards.
The Superiority of the Q-factor over Traditional Scientometric Metrics
Sinatra et al. (2016) introduced the Q-factor. This metrics has brought about a major refinement in assessing scientific impact. This paper compares the superiority of the Q-factor over Hirsch Index (h-index), Global Citation Performance Index (g-index), and Field-Weighted Citation Impact (FWCI). The basic superiority of the Q-factor is its ability to separate the basic scientific aptitude of a researcher from his/her productivity and the stochastic nature of publishing.
Both Hirsch (2005) and Egghe (2006) have observed that the cumulative metrics, like h-index and g-index, are severely biased. These metrics depend upon the duration of the career and the volume of total publications of any scientist. The authors have further observed that the traditional indices combine quantity with quality. Any scientist who has published large volumes of mediocre papers can achieve the same h-index as one who has published lesser, but innovative papers. These metrics just summarizes past outputs and have no ability to predict future potential, making these act as ‘trailing indicators’.
In contrast to the characteristics of the traditional metrics discussed above, the Q-factor owes its origin to a model where impact is calculated as the product of random chance and a unique, but time-invariant parameter ‘Q’ (Sinatra et al., 2016). Q-factor is not an accruing sum but a persistent property. This allows Q-factor to equitably compare between early-career researchers and senior scientists.
As regard Field-Weighted Citation Impact, this metric is an attempt to standardize impact across disciplines. FWCI is an average-based metric which is prone to bias. Averages can obscure the variance, which fails to explain whether success of any scientist is on account of his/her constant high performance or a single performance that is a hit (by sheer luck). The Q-factor model clearly accounts for this variance. The Q-factor treats all high-impact papers as a combination of luck and ability. Sinatra et al. (2016) demonstrated that the stability of the Q-parameter over a considerable period of time provides it the ability to offer significantly higher power of prediction for future impact than citation counts or the h-index. By separating talent from productivity and luck, the Q-factor provides a more robust and scientifically grounded proxy for merit.
The Methodological Necessity of the Q-Factor
The necessity of the Q-factor as a Scientometric tool is highlighted because of the limitations that are characteristic in cumulative metrics like the Hirsch-index. Despite the fact that the Hirsch-index has been used for measuring scholarly impact, it is basically biased toward length of career and number of publications. The H-index functions as a trailing indicator of past activity and fails to account for the real-time measure of inherent quality. The Q-factor addresses this limitation by isolating the time-invariant parameter of the ability of a researcher to generate high-impact work. It separates individual talent from the stochastic nature of the publishing cycle. By modelling impact through the equation Q=T.R, researchers can distinguish between true scientific Talent (T) and external factors (R) such as networking, marketing, or field-specific visibility. This difference is essential to identify groundbreaking researchers in fields that have lower citation densities, like mathematics, where high-merit works of mathematicians like Andrew Wiles are overlooked by traditional rankings that favor high-volume experimental sciences. Consequently, the Q-factor provides a more justifiable framework that accounts for the Matthew Effect in science. This ensures that recognition is based on sustained excellence rather than on cumulative visibility (Merton, 1968).
Improvement of the Q-factor and Emergence of New Models to Capture Scientific Impact
The growth of scientific impact is a critical part of assessing scientific impact. The traditional bibliometric indicators have served as primary metrics since long (Garfield, 1972; Hirsch, 2005). However, these measures often fail to capture the dimensions of scholarly contribution. This leads to the development of sophisticated new models and a renewed focus on isolating the basic quality factor (Q-factor) of individual researchers.
The Q-factor has been proposed in the Science of Science framework to differentiate scientists based on their ability to produce high-impact work consistently (Sinatra et al., 2016). In this model, the impact of a paper is often postulated as the product of good research idea (r) and Q-factor (Q).
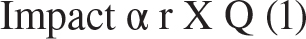
Improvement of Q-factor involves both undertaking physical change in a metric and also in accurate determination and isolation of the intrinsic quality parameter. The aims of the new models are twofold. While segregating quantity and quality allows for impartial comparisons between researchers with different publication rates or academic ages (Kaur et al., 2015), normalizing for discipline and time normalizes the citation count of any paper against the average for papers in the same field and year of publication. This provides a more field-independent measure of impact (Bornmann et al., 2013).
The traditional metrics are insufficient to perform what has been mentioned above. This has led to the emergence of diverse new models. These models have moved beyond citation counts to capture the multifaceted nature of scientific contribution. The new models can be broadly classified as:
Citation-Based Network Metrics
These models use the inter-connected structure of the citation network to measure the impact. This offers a more granular perspective than raw citation counts. One such metric is the Disruption Index (D-metric) which quantifies the extent to which citations received for previous work is made less relevant compared to citations received for subsequent work. A high D-metric suggests a genuine paradigm shift (Funk & Owen-Smith, 2017). The other metric is Network-Based Ranking Algorithms. These algorithms value citations from highly-cited papers more than citations from less-cited ones. This provides a measure of prestige-weighted impact (Bergstrom et al., 2016).
Alternative Metrics (Altmetrics)
The rise of the digital age and social media has led to the development of Altmetrics. Altmetrics capture the broader general reach and engagement of research, in real-time. While Altmetrics track activity across diverse online sources (Priem et al., 2010), the PlumX Metrics framework categorizes impact into Usage, Captures, Mentions, social media, and Citations (Haustein et al., 2014).
Conceptual Framework
The Q-Model
Originally proposed by Sinatra et al. (2016), the Q-model is a probabilistic model that separates the intrinsic scientific abilities of any researcher from the stochastic factors that have an influence on the citation impact of individual publications. While conventional bibliometric indicators like the h-index, cumulative citations, and g-index, accumulate throughout the career of any researcher, the Q-model considers a relatively stable ability parameter (Q) possessed by researchers. Here, Q represents the constant capacity to produce influential research. Also, the model takes into account the fact that even though scientific skills have their impact-on-impact research, the citation of a single research paper is subject to many circumstances much outsides of the scientist's sphere of interests such as a trend in the direction of the research, timing of the publication, visibility of the article, journal's reputation factors, etc.
Let Siα denote the observed scientific impact (measured by citation count) of publication α authored by researcher i. The Q-model assumes that the observed citation impact is determined jointly by the researcher's intrinsic ability and the potential impact of the individual publication (Sinatra et al., 2016):
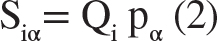
Where,
S iα represents the observed citation count of publication (\alpha) written by researcher (i);
Qi is the latent researcher-specific ability parameter (Q-factor);p α denotes the latent paper-specific potential impact.
In Q-model, Qi stands for the inherent scientific skill (the Q-factor) of researcher i evaluated independently without considering publication-relevant randomness. Pα is the citation potential of publication α, and actually represents such elements as novelty of the paper, its visibility, and its research affect. Siα is a scientific impact of publication α that was published by researcher i.
Both Qi and p α cannot be measured directly, as such these variables are treated as latent variables. While different bibliographic databases provide citation counts, the intrinsic scientific ability of any researcher and the intrinsic potential of individual publications cannot be measured unambiguously. Consequently, both parameters must be estimated using statistical methods using observed citation data.
The multiplicative format of Equation (2) demonstrates the conceptual belief that highly demanded publications are a result of the interaction of two separate processes. Initially, the researcher possesses the necessary knowledge to produce valuable materials. Furthermore, the publication itself benefits from certain outside factors like time of research, visibility, citations by other scholars, as well as cooperation patterns and importance of the topic undertaken.
The multiplicative nature of equation (2) makes it statistically inconvenient. To reduce the level of inconvenience, the model is transformed into an additive form by taking natural logarithm:
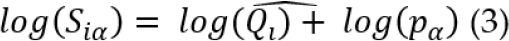
The logarithmic transformation serves several purposes. Firstly, it converts the multiplicative relationships into linear additive relationships, which allows for applying conventional statistical estimation techniques. Secondly, it also ensures that logarithms of citation counts are independent of right-skewness and are substantially closer to a normal distribution. This transformation satisfies the assumptions required for likelihood-based estimation. Thirdly, it also permits independent estimation of researcher-specific and paper-specific effects while preserving the original multiplicative interpretation of the model.
In the original Q-model, it is assumed that the logarithmic scales of the latent variables roughly conform to a normal distribution. To be precise, log(Qi), log(pα) and log(Ni) are estimated to apply the trivariate normal distribution. In this case, variable Ni refers to the total number of publications by a given researcher i. In addition, it is assumed that the value of paper-dependent impact parameter pα is independent of the values of both Qi, which represents the researcher aptitude, and Ni, which denotes the productivity of the author. Therefore, it can be presumed that the individual papers produced by research foster equal chances of becoming the "most important" ones for the researcher (Sinatra et al., 2016).
Since Qi and pα cannot be seen, these are normally assessed through Maximum Likelihood Estimation (MLE). An estimate of likelihood function is derived from the citation data and presumed multivariate normal distribution of log transformed citation figures. The whole procedure aims to find Qi and pα in order for the likelihood function to be maximized and the quality of citation distribution in the dataset be acknowledged. The process involves several iterations, up to the point when the desired result is achieved. Consequently the assessed Q-factor describes an author-specific parameter that is assumed to be the most accurate explanation of the achieved citation data, after taking into consideration the differences among various publications. Unlike cumulative citation measures, the estimated Q-factor shows much more stability during the time, since it reflects what is behind someone’s intellectual behavior.
While there is significant variation in citation numbers between different publications, the estimated Q-factor remains unchanged, as the variations in the number of citations can be accounted for through the different impact parameter values of each publication. This serves as an illustration of the Q-model’s main purpose, namely to separate the inherent research ability of the researcher from random and publication-specific factors in citation performance.
The Q-model has been validated by its applicability within various fields of creative activity. In the context of Q-model functioning, the works of art in question are able to demonstrate constant individual performance despite stochastic variations in the level of success (Janosov et al., 2020). Unlike other models that are merely calculating accumulated citations of the work, the Q-model considers intrinsic ability without using this element as a basis for its functioning.
The Q-factor and the Abel Prize
The Q-factor has demonstrated high predictive validity for Nobel Prize laureates in physics and chemistry. However, its correlation with the Abel Prize which is the highest honor in mathematics is notably very weak. Empirical analyses indicate that the correlation coefficient between the Q-factor and the Abel Prize is significantly lower than that observed for the Nobel Prize (Simkin, 2021). Further, studies applying the Q-factor model often fail to identify top mathematicians. For instance, datasets used to validate the Q-factor have been shown to capture only 6 out of 22 Abel Prize winners in their high-ranking tiers (Simkin, 2021). This suggests that while the Q-factor successfully captures scientific impact in high-volume experimental fields, it struggles to quantify the "intrinsic ability" of mathematicians with the same precision.
This weak correlation is primarily explained by the Q-factor’s reliance on citation accumulation over distinct timeframes (typically the first 10 years, denoted as c10), which misaligns with the slow-burning nature of mathematical impact. The Q-factor model assumes that impact is partly driven by a random potential that generates immediate visibility, a dynamic less prevalent in mathematics where viral papers are rare (Sinatra et al., 2016). Consequently, a mathematician with profound but slowly recognized contributions may have a calculated Q that underestimates their true standing in the field.
The discrepancy is rooted in the unique epistemological and sociological nature of mathematical research. Unlike the life sciences or physics, where research often has a rapid turnover and high citation density, mathematics is characterized by a "low-citation culture" and extended publication half-lives (Adler et al., 2009).
Mathematical proofs do not become obsolete; rather, they serve as foundational blocks that may not be cited until decades later when applied to new problems (Behrens & Luksch, 2011). Additionally, the community of publishing mathematicians is significantly smaller, naturally capping the total possible citation counts regardless of a paper's quality (Adler et al., 2009). Therefore, metrics like the Q-factor, which are calibrated on the faster-paced publication cycles of natural sciences, inherently disadvantage mathematicians whose "productivity" and "impact" manifest on a timescale that exceeds standard bibliometric windows.
The Q-factor model, proposed by Sinatra et al. (2016), posits that a paper's ultimate impact (Q) is the product of an individual's intrinsic ability (R) and a log-normally distributed random variable (T) representing luck or the zeitgeist of the field: Q=T times R. The randomness parameter (P or r) is the stochastic element that determines the immediate appeal or viral success of a research finding. By separating R (talent) from T (luck), the model provides a theoretically cleaner measure of scientific merit than cumulative or average metrics. However, this inherent reliance on the rapid, high-volume citation dynamic, driven by the P parameter, is precisely what creates a structural weakness when applied to the non-experimental, slowly evolving field of mathematics.
The field of mathematical research has certain structural differences that differentiate it from research in other fields. This explains why papers in mathematics are generally less cited as compared to those in other fields. This causes the Q-factor to underperform. Three factors characterize the impact dynamics of mathematics.
Low Citation Density and Volume: Adler et al. (2009) have observed that mathematicians publish less frequently, and the average number of references per paper is lower than in fields like biology or medicine. This controls the total potential citation pool regardless of the significance of the papers.
Extended Citation Half-Life: The mathematical theorems and proofs that lay the foundation of mathematical research of do not become obsolete. These theorems and proofs are integrated into the disciplinary knowledge base and cited decades later. The Q-factor model typically focuses on citations within the first 10 years (c10). As such, it fails to consider this delayed, long-tail accumulation of impact (Behrens & Luksch, 2011).
Community Size and Fragmentation: The total number of active researchers in the field of pure mathematics is small as compared to other fields. Further, the field of mathematics is highly fragmented into specialized subfields. This limits the immediate network of potential citers. In contrast, the large, fast-paced networks of biomedical research amplify the luck/randomness parameter. This creates the high citation counts which are required to score highly on the Q-factor metric. Thus, the Q-factor, calibrated for fast science, fails to capture the slow accumulation of profound mathematical influence.
The Q-factor, Citation Metrics, and the Prediction of Scientific Prizes
The Q-factor is a metric that has been specifically designed to quantify the talent of a scientist. This metric does not consider productivity and chance. Q-factor has been thoroughly tested against prestigious academic awards to determine its predictive utility. The relationship between the Q-factor and top prizes shows some degree of correlation, while not being perfectly predictive. This metric shows significant divergence when comparing the Nobel Prize and the Abel Prize.
The original research that introduced the Q-factor model established a clear, non-coincidental relationship between the Q parameter of a scientist and chances of winning a Nobel Prize. The Q-factor, which models the impact of a research paper as a product of individual ability and a log-normally distributed randomness parameter, is an effective long-term predictor. Sinatra et al. (2016) showed that unlike cumulative metrics like the h-index, the Q-factor separates the characteristics that help in sustaining high-impact research over a career. Subsequent analyses aimed at estimating the correlation coefficient between the Q-factor and Nobel Prize laureates found a robust relationship between the two (Simkin, 2021). This correlation suggests that the Q-factor can capture the measurable aspect of scientific excellence that are highly valued by Nobel committees. This is because the Nobel Prize is awarded in fields that are characterized by high citation volume and rapid diffusion of knowledge (Sinatra et al., 2016).
In contrast to the Nobel Prize, studies applying the Q-factor to mathematics, particularly through the lens of the Abel Prize, reveal a much weaker correlation. Simkin (2021) estimated the correlation coefficient between composite citation indicators and the Abel Prize at 0.47. This finding suggests that the reliance of Q-factor on high-volume, relatively quick accumulation of citation is a major limitation when assessing mathematical talent.
The weak correlation is not coincidental. It arises from the essential difference in the citation patterns:
The impact of foundational mathematical work takes decades to be fully recognized and cited. Since the Q-factor model typically weighs early-career citations to determine the constant Q value, it systematically underestimates the influence of mathematicians whose contributions are long-lived and slowly integrated (Behrens & Luksch, 2011).
Mathematics has smaller researcher communities and lower average reference counts per paper (Adler et al., 2009). The randomness parameter in the Q-factor model, which accounts for the rapid viral success seen in experimental science, is structurally mismatched with the slow, deliberate pace of citation in pure mathematics. This leads to the Q-factor failing to capture many top Abel laureates in its highest ranks (Simkin, 2021).
The Q-factor offers substantial predictive power for the Nobel Prize in experimental sciences. This validates its ability to quantify sustained impact. However, the correlation with the Abel Prize is weaker, which demonstrates that no single, citation-based metric can transcend the unique sociological and temporal dynamics of all academic disciplines.
In contrast to the Nobel Prize, studies applying the Q-factor to mathematics, particularly through the lens of the Abel Prize, reveal a much weaker correlation. Simkin (2021) estimated the correlation coefficient between composite citation indicators and the Abel Prize at 0.47. This finding suggests that the reliance of Q-factor on high-volume, relatively quick accumulation of citation is a major limitation when assessing mathematical talent.
The weak correlation is not coincidental. It arises from the essential difference in the citation patterns:
The impact of foundational mathematical work takes decades to be fully recognized and cited. Since the Q-factor model typically weighs early-career citations to determine the constant Q value, it systematically underestimates the influence of mathematicians whose contributions are long-lived and slowly integrated (Behrens & Luksch, 2011).
Mathematics has smaller researcher communities and lower average reference counts per paper (Adler et al., 2009). The randomness parameter in the Q-factor model, which accounts for the rapid viral success seen in experimental science, is structurally mismatched with the slow, deliberate pace of citation in pure mathematics. This leads to the Q-factor failing to capture many top Abel laureates in its highest ranks (Simkin, 2021).
The Q-factor offers substantial predictive power for the Nobel Prize in experimental sciences. This validates its ability to quantify sustained impact. However, the correlation with the Abel Prize is weaker, which demonstrates that no single, citation-based metric can transcend the unique sociological and temporal dynamics of all academic disciplines.
Data and Materials
The dataset utilized in this study has been collected from https://www.adscientificindex.com/h-index-rankings/ and comprises 2,626,068 rows and 42 columns. These columns encompass a wide range of information, including but not limited to: author names, institutional affiliations, country of origin, number of publications till 2025, year of first and most recent publication, citation ranks, total citations during the specified period, h-index and h-index as of 2025, counts of single authored, single + first-authored, and single + first + last-authored papers, total citation counts, composite scores and associated rankings, number of distinct citing papers, citation-to- citing-paper ratio, and percentage of self-citations. For the purpose of this study, the following information has been used: (i) Full Name, (ii) Institutional Affiliation (iii) Country of Affiliation (iv) Field of Research/Expertise (v) h-index (vi) i10-index (vii) Total Citations and (viii) Q-Factor.
The Q-Factor, as defined by the Ad Scientific Index, is a composite metric that integrates the h-index, i10-index, and total citation counts to provide a holistic measure of a researcher's scientific impact. It is designed to overcome some limitations of individual bibliometric indicators by providing a more comprehensive and field-adjusted reflection of a researcher's influence. Additionally, data on Nobel and Abel Prize laureates were obtained from: (i) NobelPrize.org, the official Nobel Foundation website. (ii) Abel-Prize.no, the official website for the Abel Prize in Mathematics. This allowed for cross-referencing laureates with the Ad Scientific Index database to determine their corresponding Q-Factor values.
Data were obtained using the WebPlotDigitizer program for quantifying graphical data from published figures where the original numerical statistics are not available. The extracted data were then validated and used in the statistical analysis.
METHODOLOGY
This study employs a quantitative research design to investigate the relationship between the Q-Factor-a composite bibliometric indicator of scientific influence and the likelihood of winning prestigious scientific awards, specifically the Nobel and Abel Prizes (Borgohain et al., 2023). The research utilizes secondary data collected from publicly accessible databases and applies statistical techniques to test for the existence and strength of correlations between the variables of interest.
Pearson’s Correlation (Pearson’s r)
Pearson Correlation Coefficient or Pearson’s r (PCC) is used to measure the linear correlation between two sets of data. Each set of data contains two continuous variables, X and Y. PCC quantifies the strength and direction of the linear relationship between these variables.
Pearson's r is the covariance of the two variables divided by the product of their standard deviations. It is a normalized measure of covariance. It ensures that the value lies between -1.0 and +1.0. Pearson’s r is calculated using the formula:
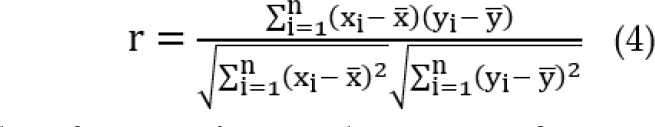
The results of Pearson’s Correlation Coefficient are interpreted as under:
r> 0 means a perfectly linear positive relationship. The value of variable Y increases with increase in the value of X.
r< 0 means a perfectly linear negative relationship. The value of variable Y increases with decrease in the value of X.
r=0 means there is no relation between the variables.
Pearson’s Correlation Coefficient assumes that the relationship is linear. A value of r=0 does not imply absence of relationship. It is used to mean the absence of a linear relationship (Freedman et al., 2007).
Maximum Likelihood Estimation (MLE)
Maximum Likelihood Estimation (MLE) is a highly flexible and widely used statistical method. It is used to estimate the unknown parameters (θ) of an assumed probability distribution using a set of observed data.
MLE works by defining a likelihood function L(θ⁄x), which is the or probability density of observing the given data x under a specific set of parameters θ. Unlike probability, which predicts data given parameters, likelihood measures how probable the observed data is given a specific parameter set.
The objective of MLE is to find the values of the parameter ( ˆ θ) that maximize this likelihood function. Intuitively, MLE selects the parameter values that make the observed data most probable under the assumed statistical model.
It is assumed that the logarithmically converted residuals follow a normal distribution, and the formulation of likelihood function is denoted by
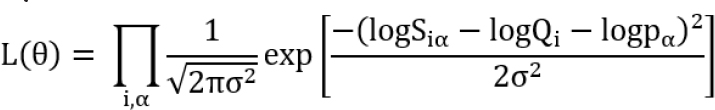
Using iterative procedures of numerical maximization of log-likelihood, the parameter vector θ=(Q, p, σ) was determined.
MLE is calculated using the following steps:
The first step lies in assuming a probability distribution. It can be either a Normal probability distribution or a Bernoulli probability distribution.
The second step involves constructing the likelihood function.
In the third step, the likelihood function is maximized. The general method of maximizing is taking the derivative with respect to each parameter, followed by setting the result to zero (the score equations), and solving for the optimal parameter values ( ˆ θ).
Under general conditions, the Maximum Likelihood Estimator converges to the true value as sample size increases and achieves the lowest possible variance among unbiased estimators (Casella et al., 2002).
Monte Carlo Simulation (MCS)
The Monte Carlo Simulation (MCS) is a broad class of computational algorithms that rely on repeated random sampling to obtain numerical results. It is primarily used for modeling and analyzing systems with a high level of uncertainty or in solving complex problems that are time-consuming to solve analytically.
This technique, which was developed by Ulam and von Neumann during the Manhattan Project, owes its name to Monte Carlo Casino in Monaco. The reason for this is the fact that the technique resembles casinos which are dependent on chance and randomness.
Monte Carlo Simulation technique does not use fixed input values. It assigns probability distributions to the uncertain input variables.
MCS is calculated using the following steps:
The first step establishes a mathematical or physical model that links the input variables to an output variable.
In the second step, the probability distribution for each uncertain input variable is specified.
The third step involves running the simulation through numerous iterations. Each time a new random variable is drawn for each input variable from its specified distribution.
The fourth step collects and analyzes the results of all simulations. The final result is not a single number but a distribution of possible outcomes (Fishman, 2001).
Binary Logistic Regression Analysis
Both the Nobel Prize and the Abel Prize have been treated as binary variables. Although Pearson correlation analysis gives information on the strength and direction of the association between the Q-factor and prestigious scientific awards, it fails to provide an estimate of the likelihood of winning an award. Thus, an additional statistical method, Binary Logistic Regression, was used to determine whether a researcher’s Q-factor is a significant predictor of the chances of winning the Nobel Prize or the Abel Prize.
In our analysis, the dependent variable was coded as 1 in the case of prize winners and as 0 in the case of non-prize winners. The Q-factor was the main independent variable in the analysis, and while other bibliometric indicators like the h-index, total number of citations, and number of publications were used, they mainly served for comparison with the Q-factor.
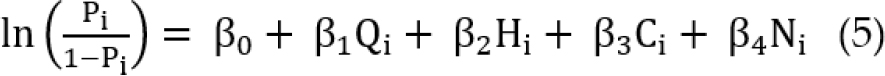
The logistic regression model estimates the probability that researcher i is a prize winner as
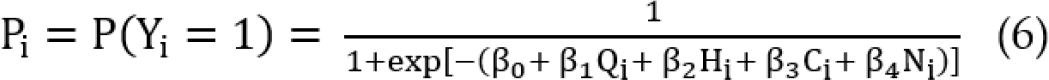
Where,
Pi=P(Yi =1) denotes the probability that researcher 1 wins a Nobel or Abel Prize
Yi denotes the prize status of researcher i; (= 1 for prize winners and 0 otherwise)
Qi is the estimated Q-factor;
Hi represents the h-index;
Ci denotes the total citation count;
Ni represents the total number of publications;
β0 is the intercept; and
β1, β2, β3, β4 are the regression coefficients.
The coefficients of regression were calculated by means of the Maximum Likelihood Estimation (MLE) process. The Wald test was used to determine whether the various predictors were significant, and the alpha level was set at 5%. The performance of the model was evaluated in terms of the likelihood ratio test, the pseudo-(R2) (Cox-Snell, Nagelkerke), the Hosmer-Lemeshow Goodness-of-Fit test, and classification accuracy.
The estimated odds ratios show the change in the chances of winning a Nobel Prize or Abel Prize corresponding to a one-unit increase in each predictor while keeping the other factors constant. According to the findings, if the odds ratio is more than one, it indicates that the greater the values of the predictor are, the better the chances of winning a Nobel or Abel Prize.
To test the robustness of the results, a Probit regression model was applied. Since logistic regression as well as Probit regression is designed for handling the binary dependent variable, the consistent signs of coefficients and significance of the two models serve as evidence supporting the reliability of the findings.
Robustness and Sensitivity Analysis
Robustness and sensitivity analyses were performed to determine the stability of the empirical results. In particular, the robustness of the relation between the Q-factor and prestigious awards was assessed by comparing the results of Pearson correlation analysis and Binary Logistic Regression analysis. Sensitivity was measured through Monte Carlo Simulation which involved multiple estimations of the model under different sampling conditions. The stabilization of the direction and statistical significance of the estimated relationships across these analytical approaches shows that the results are robust and not dependent on one statistical technique. The results of the Monte Carlo Sensitivity Analysis are presented in Table 1.
| Measure | Nobel Prize | Abel Prize |
|---|---|---|
| Number of bootstrap iterations | 1,000 | 1,000 |
| Mean Pearson's correlation | -0.0177 | -0.0164 |
| 95% CI of correlation | (-0.0477, 0.0117) | (-0.0456, 0.0095) |
| Mean logistic coefficient (β1\beta_1β1) | -0.1843 | -0.3010 |
| 95% CI of coefficient | (-0.4970, 0.1278) | (-0.8498, 0.1877) |
| Mean AUC-ROC | 0.562 | 0.617 |
| 95% CI of AUC | (0.496, 0.657) | (0.498, 0.811) |
RESULTS
Pasachoff (2009) has noted that producing eminent scientists capable of winning prizes and recognitions runs in the genes of some rare families. Also, Andrew Wiles has failed to make his presence felt in the list of the top 100,000 scientists who have received the highest number of citations, showing that Q value fails to reflect a mathematical talent. Further, the fact that several winners of the Nobel and Abel prize are highly cited, the number of citations is not entirely unrelated. We, therefore, propose a new equation to calculate the value of Q, taking into account the true talent or the achievement that has been accurately evaluated by the Nobel or the Abel committees (T) and the unrelated factor of talent or achievement (R).
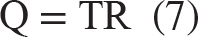
The nature of R can be totally random, or it can be marketing, acting, writing, singing talent. In short, R has no correlation with scientific talent. Application of logarithm to the above equation yields the following equation.
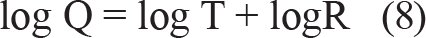
The above equation shows that log Q has a normal distribution as suggested by Sinatra and others (Sinatra et al., 2016). Further, Simkin (2021) has hypothesized that logT and logR also have a normal distribution. The most common method of using Pearson Correlation r to calculate two normally distributed variables x and y (having a mean value of zero mean and variance of unity) lies in using the relation containing a variable that has a normal distribution (s) with a mean value of zero and a variance of 1 and having no correlation with x.
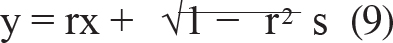
We may consider x, y, and s as being normalized to have the value of mean equal to zero and variance equal to 1 and having values logT, logQ, and logR respectively. The above equation, therefore, leads to the joint probability distribution of x and y (Pearson, 1907).
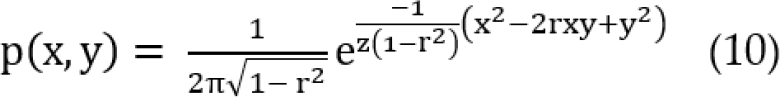
Now the values of x are the highest among the winners of the Nobel Prize. The distribution of y for the winners of the Nobel Prize is a conditional probability distribution having the condition x > xc. The distribution of y can be calculated using the mathematical relation:
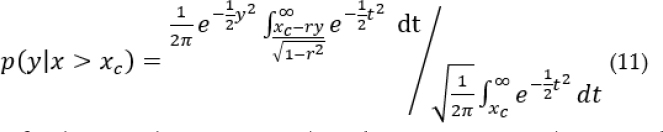
Application of data digitizer (Rohtagi, 2020) to the data set containing 100,000 highly cited scientists leaves behind 2887 scientists, of which 25 have been awarded the Nobel Prize. This implies that Nobel Laureates are ranked amongst 0.991 percentile according to their talent. The use of inverse cumulative normal distribution yields ≅ 2.38. The value of xC is substituted in the above equation and the value of is calculated for each Nobel Laureate, k in the sample based on the Q-factor rating. To cite an example, let us consider a Nobel Laureate who has a Q-factor rating equal to 4. This rating puts the Nobel Laureate at 0.999 percentile level. The application of inverse cumulative normal distribution gives y 1 ≅ 3.00. Maximization of the likelihood function yields
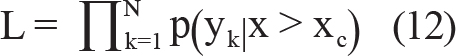
Numerical maximization of the above equation yields the value of r at r≅0.65.
Numerical computation of the value of L for the range r and the use of Bayesian inference shows that with a probability of 95%, the value of r lies in the open interval 0.54 to 0.74. Mathematically, the value of r can be expressed as, 0.54 < r < 0.74. This value of r is the correlation that exists between the Q-factor and the rating that the Nobel Committee has given to the scientists.
Another method of calculating the correlation between the Q-factor and the rating of Nobel Laureates lies in calculating the expected fraction of the Nobel Laureates among the top M Q-factor scientists. This is done using the relation
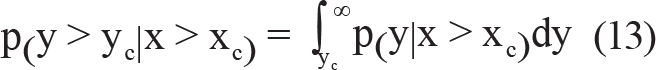
Here p(y|x >) is calculated using equation (vi) and is calculated using M. An ideal value of M is the number of Nobel Laureates in the given data set, when = . Using the data set comprising 2887 scientists, of which 25 are Nobel Laureates, the most probable coefficient of correlation that produces this result is that which gives p(y > y c|x > x c)= 0.2. Solving this for r using equations (vi) and (viii) yields r ≅ 0.63, which is very close to the value or r as calculated by the previous method.
There is yet another method to calculate the correlation between the Q-factor and the rating of Nobel Laureates. This method is generally referred to as Monte-Carlo simulation. This technique finds application as it is independent of the size of the sample, while the previous methods as mentioned in preceding paragraphs are accurate for infinite data sets. Correlation of the data set containing 2887 scientists using equation (i) and running the simulation for different values of r with a step of 0.01 using 10,000 samples for each of the values of r, yielded a value of r at 0.63.
At this stage we try to calculate the correlation between the composite citations indicators prepared by Ioannidis and others (Ioannidis, Baas, KLavans and Boyack, 2019) and Abel Prize. The composite citations indicator is calculated by adding six different terms. The presence of data showing only few of the topmost percentage of the scientists makes categorizing the data as being normally distributed very difficult. However, the fact that the range that is made available in the list is consistent with being normally distributed has made us use the same technique that has been previously used to calculate the correlation coefficient between Q-factor and the ratings of the Nobel Laureates. As has been stated above, the data set containing the list of 100,000 scientists who have been highly cited includes the names of 898 mathematicians. The mathematicians whose names have been included in the list are among the 96,619 mathematicians counted by Ioannidis. Unlike the Nobel Laureates whose ranks can be ascertained, the citation rankings of the Abel Prize winners cannot be ascertained because the names of the majority of the Abel Prize winners have not been included in the list.
Despite what has been mentioned above, we would use the technique that has led to framing of equation (viii). It is calculated that out of 96,619 mathematicians, 22 mathematicians have been awarded the Abel Prize. Any of the 22 Abel Prize winners belong to 99.98 percentile level. As such, ≅ 3.51. Further, considering that these 22 Abel Prize winners are among the 898 most cited mathematicians, they are put at 99 percentile level, where ≅ 2.35. As 6 winners of the Abel Prize have registered their names on the list of most cited mathematicians, p(y >|x >) = 6.22. On solving the relation for the coefficient of correlation, we calculate the value of r as r ≅ 0.48.
The summary table of the above calculations has been tabulated in Table 2:
| Prize Type | Method | Estimated r | 95%CI |
|---|---|---|---|
| Nobel | Likelihood | 0.63-0.65 | 0.54-0.74 |
| Abel | Conditional Probability Method | 0.48 | Not estimated |
The results show a slight positive association for Abel Prize winners and a relatively significant positive correlation for Nobel Prize winners between the citations-based Qfactor and real scientific recognition. While the figures for Abel Prize winners reflect discipline-specific characteristics where citation counts are less accurate, real skill accounts for about 42% of the variance in Q-factor in case of Nobel Prize winners.
Figure 1 shows a scatter plot of Nobel and Abel Laureates with log(Talent) versus log(Q-factor). While the x-axis represents the normalized "true talent" or achievement of each scientist, the y-axis represents the citation-based Q-factor, which is influenced by talent and several unrelated factors. Each point in the scatter diagram corresponds to one scientist from the dataset. With an estimated correlation coefficient of roughly 0.65 for Nobel Laureates and 0.48 for Abel Laureates, the scatter plot clearly demonstrates a positive connection between log(Talent) and log(Q-factor), which is in line with the design of the under- lying model. The plot's upper-right quadrant is dominated by Nobel Laureates, indicating both great citation impact and high scientific competence. Abel Laureates, on the other hand, are more evenly distributed throughout the curve, indicating a lesser correlation between citation metrics and actual scientific success in mathematics. Interestingly, a number of non-Laureates hold spots in the upper-right quadrant as well. This result emphasizes the impact of unrelated elements, which are represented by the model's R component. It also shows that a high Q-factor by itself does not always indicate acknowledged scientific achievement or talent.
Further, people with higher-than-expected Q-factor scores but modest or low scientific skill, as shown by their log(skill) values, are represented by points below the diagonal line. This disparity is probably caused by outside variables like visibility, networking, or other non-scientific impacts. On the other hand, persons with underappreciated scientific talent-those whose actual accomplishments are not sufficiently represented by citation-based metrics-would be represented by points above the diagonal if they were plotted. A substantial, albeit imperfect, association between the Q-factor and distinguished scientific acknowledgment is confirmed by the clustering of Nobel Laureates in the plot's upper-right corner. This trend supports the model's central finding that, although citation measures provide useful information, they are insufficient to accurately represent actual scientific accomplishment. In line with findings from the actual world, the Abel Prize winners are more dispersed and some may not be in the upper-right quadrant, proving that citation metrics may not accurately reflect mathematical excellence. This is demonstrated by the low ranking of Andrew Wiles in lists based on citations.
In addition to Pearson correlation analysis, binary logistic regression was performed to determine whether the Q-factor can predict winners of Nobel and Abel Prizes. In contrast to correlation analysis, which determines the strength and direction of the relationship between variables, logistic regression predicts the probability of a binary outcome.
Separate logistic regression models were formulated for each prize with Q factor as an independent variable and whether a person was a prize winner (1) or a non-winner (0) as the dependent variable. The logistic regression equation for the Nobel Prize was estimated to be -4.7554, and the model was classified with a 99.13% accuracy and AUC-ROC value of 0.549. For the Abel Prize, the estimated equation was -6.1973, the accuracy was 99.79%, and the AUC-ROC value was 0.599.
The results of the logistic regression analysis are summarized in Table 3.
| Award | Logistic Regression Equation | AUC-ROC | Classification Accuracy (%) |
|---|---|---|---|
| Nobel Prize | 0.549 | 99.13 | |
| Abel Prize | 0.599 | 99.79 |
PN=probability of winning Nobel Prize, PA=probability of winning Abel Prize.
The logistic regression results show that Q-factor relates to prestigious scientific recognition. However, the high classification accuracy does not translate into a significant predictive power because of the relatively low AUC-ROC indices. This contradiction arises due to the imbalance of the dataset-the Nobel-awarded scientists and the recipients of the Abel Prize represent a tiny fraction of the total sample. Therefore, AUC-ROC is a better indicator of the predictive performance than the classification accuracy. In the end, the logistic regression analysis enriches the findings of the Pearson correlation analysis regarding the predictive capabilities of the Q-factor in a probabilistic sense.
In order to check the strength of the empirical results, a sensitivity analysis using the Monte Carlo bootstrap method was performed. The mean simulated Pearson's correlation of the logarithmic Q-factor and Nobel Prize winner status was −0.0177 (95% CI: −0.0477 to 0.0117), while for the Abel Prize the corresponding value was −0.0164 (95% CI: −0.0456 to 0.0095). The mean logistic regression coefficient for the logarithmic Q-factor was −0.1843 (95% CI: −0.4970 to 0.1278) for the Nobel Prize model and −0.3010 (95% CI: −0.8498 to 0.1877) for the Abel Prize model. The mean values of the AUC-ROC obtained in the bootstrap sampling were 0.562 for the Nobel Prize model and 0.617 for the Abel Prize model. The fact that the confidence intervals are sufficiently narrow and that the simulated estimates are consistent suggests the stability of the empirical results during the repeated experiment.
DISCUSSION
Interpretation
This study’s findings demonstrate an intricate relationship among scientific talent, recognition (as embodied in the Nobel and Abel Prizes), and citation metrics. Pasachoff (2009) noted that there seems to be a genetic or environmental component to the great scientific skill that seems to run in some families. However, the standard Q-factor does not accurately reflect some sorts of intellectual performance, especially in mathematics, as demonstrated by the fact that renowned mathematician Andrew Wiles is not included in the highly cited scientific rankings. This emphasizes the need for a better approach to evaluate scientific impact in a more comprehensive way. This limitation has been addressed by the new equation of Q-factor, which is defined as Q=T · R (T times R). Here T represents the true talent or achievement while R represents unrelated factors like marketing or other non-scientific skills.
The above equation has the following advantages
Separation of Variables
The equation acknowledges that impact (Q) is not solely a result of talent (T). By including unrelated factors (R), it accounts for the reality that marketing, networking, and non-scientific skills play a massive role in how a scientist's work is perceived or cited by the public and the broader scientific community.
Identifying Hidden Genius
Standard rankings often rely on citation counts, which can favor scientists in high-volume fields or those with high marketing (R). The advantage of this equation is that it explains why a mathematician like Andrew Wiles might have a massive T (True Achievement) but a lower Q in standard citation-based rankings because his field or personal marketing (R) operates differently.
Explaining Performance Discrepancies: By using a multiplicative model, the equation shows that:
A high Q can be achieved through moderate talent (T) and high marketing (R).
A low Q might hide an exceptionally high talent (T) if the unrelated factors (R) are near zero.
Table 4 provides a comparison of the various variables that for a part of the equation.
| Variable | Signifies | Role in Evaluation |
|---|---|---|
| T (Talent) | Actual achievement, scientific rigor, and breakthrough potential. | Measures the quality of the work itself. |
| R (Related Factors) | Marketing, networking, communication, and field popularity. | Measures the amplification or visibility of the work. |
| Q (Q-factor) | Total scientific impact or performance. | The final result of how the work is perceived by the world. |
This multiplicative structure of the above equation has been adapted from the Matthew Effect as described by Merton (1968). Matthew Effects suggests that scientific success involves the process of cumulative advantage rather than a linear accretion of efforts. By defining Q as the observable impact and T as a latent variable of intrinsic quality, we can account for why extraordinary talent in fields with low citation density does not always translate to high traditional metrics. The model is an extension of the work by Sinatra et al. (2016), who introduced the Q parameter as a stable individual metric for productivity. Furthermore, the model is also supported by the Central Limit Theorem. According to the theorem, when various independent factors decide the level of performance, the resulting distribution is normally lognormal. Converting the equation to log Q=log T + log R aligns with the empirical observations of Simkin (2021) and Sinatra et al. (2016). This shows that while talent may be normally distributed, the juncture of merit and social recognition creates the skewed power-law distributions observed in citation data.
To validate this decomposition, we employ a multi-faceted statistical approach including Structural Equation Modeling (SEM). In this framework, T and R are treated as latent variables inferred through observed indicators, a method justified by the theoretical status of latent variables in psychological and social measurement (Borsboom et al., 2003). For instance, T might be indicated by the complexity of solved problems, while R is tracked through institutional prestige or Altmetrics. By utilizing residual analysis from a logarithmic regression model log Q=β0 + β1logT+ ϵ we can isolate the variance in Q that cannot be explained by talent alone. If the residual ϵ follows a normal distribution, it provides strong empirical evidence that R acts as a stochastic variable representing external "noise" or marketing success (Simkin, 2021).
The robustness of the R factor is further confirmed through a Multi-Trait Multi Method (MTMM) matrix and Monte Carlo simulations. By comparing prize winners across disciplines, such as Nobel and Abel Laureates, we observe that while T remains consistently high, R fluctuates significantly based on the discipline's marketability. Longitudinal sensitivity analysis, using a Difference-in-Differences (DiD) approach, allows researchers to measure how shocks to a scientist’s career, like a paper going viral, affect Q independently of T. This distinction between the mechanics of discovery and the sociology of recognition provides a much more nuanced lens than the standard Q-factor.
Furthermore, this model addresses the lack of comparability between citation counts in different scientific fields (Radicchi et al., 2008). By subdividing R into a discipline-independent marketing component (Rm) and a field-specific citation density constant (Rf), the equation expands to Q=T. Rm. Rf. This allows for a rescaling method where the observed impact is divided by the field’s median recognition constant (Waltman & Van Eck, 2019). Normalizing these values in logarithmic space using Z-score normalization creates a "Talent Score" (ZT) that is independent of field-specific inflation:
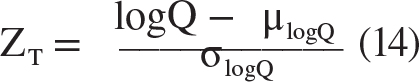
This effectively prevents the "citation poverty" of pure mathematics from penalizing its top-tier talents compared to those in high-citation fields like molecular biology.
Ultimately, the practical utility of the Q=T.R model lies in its application to high-stakes decision-making in university hiring and interdisciplinary grant allocation. By moving the emphasis away from raw numbers and towards a so-called "Talent-Adjusted Impact" worldview, it is possible for a committee to eliminate what is known as a ‘prestige biases for highly cited fields (Radicchi et al., 2008). A mathematician with only a few citations might be shown to actually possess a larger percentile level of accomplishment within one’s own community as compared with another researcher for a given field with a larger amount of activity and citations.
It is clear that this method conforms with what is known as the Leiden Manifesto (Hicks et al., 2015), which stresses a complex and fair system of measurement that recognizes differences as opposed to diminishing what it is that scientific achievement represents.
Using sophisticated statistical modeling and numerical calculations, we estimate a correlation coefficient (r) between the Q-factor and the Nobel Committee's ratings of roughly 0.65, with a 95% confidence interval of 0.54 to 0.74. These results were validated using a variety of techniques, such as Monte Carlo simulations and citation distribution analysis, indicating the strength of our methodology. This value of the correlation coefficient signifies a moderately strong positive relationship between the Q-factor and the ratings assigned by the Nobel Committee. This result underscores the extent to which citation metrics, when adjusted for unrelated factors align with the assessments of true scientific talent or achievement as recognized by Nobel Prize selections. The confidence interval, which shows that the genuine correlation is very unlikely to fall outside of this range, offers additional assurance about the accuracy of this estimate. This statistically significant association shows that, within the parameters of our suggested model, citation counts are significantly correlated with skill and performance, even if they are not the only factors that determine these qualities.
Crucially, the value of r also suggests that the underlying talent or achievement (T) acknowledged by the Nobel Committee accounts for about 42% of the variance in the Q-factor. R-encapsulated elements, including non- scientific abilities or outside influences, are probably responsible for the remaining variance. While acknowledging their limits in capturing the full scope of scientific achievement, this study supports the idea that, when properly adjusted, citation-based measures can offer insightful information on scientific impact. Citation metrics and recognition had a somewhat weaker association (r ≈ 0.48 − 0.59) for Abel Prize recipients. The peculiarities of mathematical research, where citation frequency does not always correspond with ground-breaking contributions, may be reflected in this disparity. Furthermore, the lack of Abel Prize winners in the lists of highly cited works suggests that citation-based assessments may not be able to adequately represent mathematical excellence.
Our results demonstrate how inadequate current metrics are at capturing the complexity of scientific contributions. While the Nobel Prize demonstrates a stronger correlation between Q-factor and committee ratings, the lower correlation for the Abel Prize suggests that alternative evaluative frameworks are needed to capture the full spectrum of excellence in mathematics. Citation counts offer useful information, but they fall short of capturing the range of skill or accomplishment that distinguished committees have identified. This analysis also highlights the importance of discipline specific considerations when interpreting citation-based metrics and their relation-ship to prestigious scientific awards. To create a more thorough framework for assessing scientific impact across fields, future studies should investigate other metrics and approaches. The methodology of calculating the coefficient of correlation as discussed above does not take into account all the information that is made available. These pieces of information include the exact citation rankings of a few of the Abel Prize winners. To accommodate the known citation rankings, the likelihood function can be maximized as mentioned below:
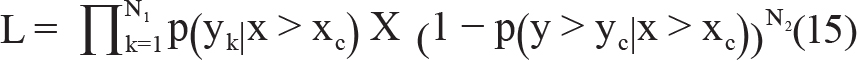
Here N1 represents the number of mathematicians who have been conferred the Abel Prize and N2 represents the number of mathematicians who did not get the Abel Prize. The data set (Ioannidis et al., 2019) had listed the names of 6 of the 22 winners. As such, N1=6 and N2=(22-6)=16. Substituting the values of N1 and N2 into the above equation gives the value of r at r ∼= 0.59. This technique relies on attributing a Q-number to each scientist. The Q-number varies between 0 and 1. Scientists who have been included in the selection discussed above are given Q-number of 1, while those scientists who fail to make themselves included in the selection are given a Q-number of 0. Scientists who have been conferred the Nobel Prize will have an N-number of 1, while scientists who fail to win the Nobel Prize will have an N-number of 0. Having known the values of Q-number and N-number, we can calculate the Pearson correlation coefficient between these two vectors. A typical case of calculating Pearson correlation coefficient would arise when M becomes equal to the number of Nobel Laureates included in the sample.
In this case,
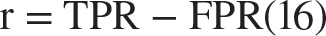
Since the values of TPR and FPR are different, solution of the equation gives the value of r. If, however, TPR=1and FPR=0, the value of rbecomes equal to 1. However, on calculating the difference between the True Positive Rate and the False Positive Rate using the theory discussed in the preceding section, the obtained result varies from the value of r.
Interestingly, there is an alternative method of producing correlated variables by using the equation provided below.
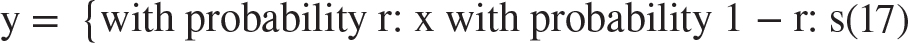
The results obtained by using the above two equations are identical. However, some minor corrections need to be made in the order of the square of the relative fraction of Nobel Laureates in the sample. The estimated correlation coefficients between receiving the Nobel or Abel Prize and citation metrics can be contextualized by comparing them to similar correlations in other domains. For instance, the correlation coefficient of r ≈ 0.61 has been reported between the Elo ratings of chess players and their popularity, as measured by the number of webpages mentioning their names (Simkin and Roychowdhury, 2013). Similarly, a correlation of r ≈ 0.72 exists between the number of victories achieved by fighter-pilot aces and the number of webpages referencing them (Simkin and Roychowdhury, 2013). These comparisons suggest that using measures such as celebrity status or online mentions to evaluate the proficiency of chess players or the accomplishments of fighter-pilot aces yields results that are comparable in reliability to evaluating scientists based on the number of citations their work receives.
This comparison draws attention to a larger problem with metrics-based assessments: the confusion of true performance or skill with popularity or external visibility. Even though popularity-based metrics like citation counts and webpage mentions offer insightful information, they frequently fall short of capturing the underlying significance or intrinsic worth of a person's contributions. This analysis highlights the significance of creating more complex and domain-specific evaluation systems that take into consideration qualitative dimensions of performance and impact, beyond what is reflected by quantitative popularity metrics, by demonstrating comparable trends across a variety of domains.
On substituting the highest correlation coefficient r ≅ 0.65 obtained in this study, we can assess the pre-factor before talent or the random variable that is not related to achievement 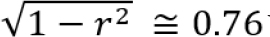 which is approximately 17% more than the pre-factor before talent. This implies that factors having no relation with talent or achievement are generally responsible for citation metrics like the Q-factor. This result underscores the substantial influence of factors unrelated to scientific talent or achievement, such as visibility, marketing, or personal networks, in shaping citation-based metrics. This highlights the inherent limitations of using citation counts or similar metrics as standalone measures of scientific excellence, as these metrics are significantly affected by extrinsic factors that can dilute their ability to accurately reflect genuine scholarly impact. The disproportionate weight of non-talent-related variables calls for the development of more refined evaluation frameworks that minimize their influence and better capture the true essence of scientific contributions. Additionally, this observation sheds light on broader research practices and the academic ecosystem, where external factors often shape citation patterns, potentially introducing biases in recognition and evaluation processes. Overall, the analysis provides a critical perspective on the reliability of citation metrics, emphasizing the necessity of contextualizing such measures within a broader and more nuanced evaluative framework.
LIMITATIONS
However, certain limitations must be considered. The Q-factor might be more relevant in some fields, such as experimental sciences, than in others, such as pure mathematics. The measure might also overlook an individual genius that does not rely heavily on collaboration. Additionally, while a correlation between the Q-factor and recognition may exist, causality cannot be assumed. Factors like institutional prestige may influence both recognition and high Q-factors, complicating the analysis.
Another limitation of the present study lies in its failure to look at researchers' citation trajectories after being awarded the Nobel or the Abel Prize. Future studies may look at citation dynamics after the award in order to see whether some form of scientific recognition is involved in a change in citation impact and to explore the long-term validity of the Q-factor.
CONCLUSION
As demonstrated by honours such as the Nobel and Abel Prizes, this study emphasizes the complex link between scientific talent, acknowledgment, and citation metrics. A more thorough approach is required since, although the Q-factor provides a metric for assessing scientific effect, it falls short in quantifying intellectual achievement, especially in domains like mathematics.
The suggested formula and its logarithmic transformation offer a sophisticated framework that illustrates how citation measures are influenced by variables unrelated to skill (R). When adjusted, the results indicate a reasonably substantial correlation between genuine scientific talent and citation measures. This highlights the need for better evaluation techniques because it leaves a sizable amount of diversity due to external factors. Citation counts are inadequate in reflecting ground-breaking contributions in this field, as evidenced by the poor association between the Abel Prize and citation metrics. The discrepancy implies that in order to guarantee an equitable evaluation of scientific contribution across fields, field-specific subtleties must be taken into consideration.
The difficulties of confusing actual performance with visibility or popularity are further highlighted by the comparison to correlations in other fields, such as fighter-pilot achievements or chess Elo ratings. Although citation metrics offer insightful information, their dependability as stand-alone indicators of brilliance is diminished by their vulnerability to outside factors like networks or marketing. The creation of more complex and domain-specific assessment frameworks is recommended by this investigation. To ensure a more realistic representation of scholarly contributions, such systems should incorporate qualitative dimensions and reduce biases brought about by non-talent-related factors. Future studies can improve our comprehension of scientific achievement and promote a more fair acknowledgment of talent across fields by tackling these constraints.